
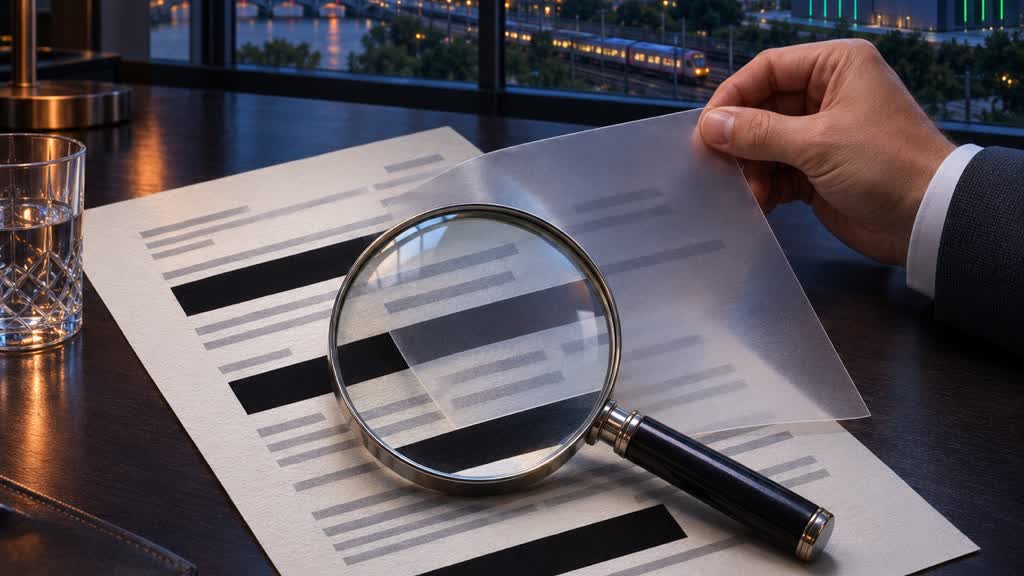
The black bars look convincing. The text underneath may still be available to the next AI tool that reads the file.
A black rectangle is not proof that the information has gone
Your team asks an AI assistant to remove customer names from a PDF. The returned document has neat black bars in all the expected places. Someone checks the preview, attaches it to an email and moves on. That is a plausible workflow, but the preview answers only one question: what does this viewer display? It does not establish what another person or another extraction tool can recover from the file.
A PDF can contain visible page content, a separate searchable text layer, comments, document properties and attachments. A rectangle drawn over a name may obscure the page without removing the underlying text. A scanned page can also have optical character recognition text that needs attention separately from the image. Which elements survive depends on how the file was produced and how the redaction tool works.
AI makes this distinction more important because the next recipient may not read the document visually at all. They may upload it to a search system or ask an assistant to summarise it. A system that extracts retained text can encounter information that a human looking at the page cannot see. This is a file-handling risk, not evidence that a particular model can reverse every genuine redaction.
The practical standard is therefore simple: the material must be removed from the released file, not merely hidden from its default view. Treat the AI result as a candidate document until checks are complete. Keep the original restricted, save a separate release copy and give the reviewer that exact copy. A screenshot of black bars is not a release certificate. Neither is the assistant saying that the task has been completed successfully.
Approve the released file, not the reassuring appearance of the page.
Separate finding sensitive information from removing it
AI can be useful at finding candidate information. It may recognise a customer name mentioned in an unusual sentence, connect a trading name with a person, or spot details that a simple search pattern misses. Those capabilities do not establish that every sensitive item has been found, and they do not establish that the underlying PDF objects have been removed. Keep the finding stage and the file transformation stage distinct.
Adobe's redaction instructions, updated on 31 August 2026 provide a concrete example of that separation. They describe selecting text or images, choosing Apply, deciding whether to sanitise and remove hidden information, and saving the resulting document. Marking a passage and applying the redaction are not interchangeable actions. These are documented product steps, not a claim that buying a licence guarantees a correct outcome.
In practice, write down what needs removing before asking a tool to find it. A supplier dispute might require personal mobile numbers and individual bank details to be withheld, while leaving company names and invoice totals readable. A customer disclosure request may require a different decision about third-party information. An instruction such as make this safe is too vague to provide a reviewable boundary. The person responsible for disclosure must define that boundary.
Use AI suggestions to assemble a review list, then use an approved redaction function to remove the agreed material. Check uncertain items rather than letting the model silently decide the legal basis for disclosure. Finally, verify the saved output independently. If the same assistant both transforms the file and declares it safe without inspecting its actual contents, you have a repeated assertion rather than a second control. Record who made the disclosure decision and who checked the file.
Detection, permanent removal and release verification are three different jobs.
Hidden content deserves its own inspection
Names on the page are only part of the problem. A comment might identify the colleague who raised a sensitive concern. Document properties may retain an author name or an internal title. An attachment may contain the original unredacted spreadsheet. A hidden layer can hold material that is absent from the default view. Not every PDF has these features, but a release process should check rather than assume that it does not.
Adobe's sanitisation guidance, updated on 22 October 2026 explicitly names metadata, comments and hidden layers. It offers both a Remove all route and selective removal through a Hidden Information panel. This is a second named example of an existing product capability businesses can assess before building a custom AI workflow. The important procurement question is what your installed version actually removes from the kinds of files you distribute.
What this means in practice is a separate hidden-content check after the visible redactions have been agreed. Review attachments, comments, properties and any available layer information. Save the sanitised file under an unmistakable release name, close it and reopen it from its destination folder. Do not send the original because it happens to be the first attachment suggested by the email client. Keep working versions away from the release folder.
Be careful with blanket sanitisation too. Removing document features can affect links, forms, accessibility information or other useful functions. The objective is a safe and usable disclosure, not a file that nobody can navigate. Test the intended recipient journey after cleaning. If the document needs accessible structure, agree how that structure will be preserved or restored without reintroducing the withheld information. Record exceptions explicitly instead of quietly treating them as somebody else's problem.
A clean page can still travel with comments, metadata or attached originals.
Test with fictional secrets before trusting live documents
The easiest demonstration is not a real customer contract. It is a synthetic document containing fictional details that you can safely try to recover. Put an invented person's name in the visible page, another in a comment, and a distinctive fictional reference in document properties. Include a scanned page with an OCR layer and, if your workflow accepts them, an attachment. The pack should resemble the documents your staff actually receive.
Run that pack through the exact workflow you intend to approve, including the AI account, redaction tool, export option and final storage location. Reopen the saved output in another viewer. Try selecting and copying text across the redacted areas. Search for the known fictional markers and extract the text with an approved local tool. Inspect the available comments, attachments and properties. No single search proves complete removal, but several independent checks can reveal a straightforward failure quickly.
For illustration, a small test might contain twelve deliberately planted items across four document types. Those numbers are a suggested exercise, not a benchmark or a reported study. Log each item, where it was placed, whether the workflow detected it, and whether it remained recoverable after release. Separate detection failures from removal failures: a missed name needs a different remedy from a name correctly selected but left behind in the text layer.
Do not upload the confidential original to a public chatbot to test whether its redactions worked. That could create the very disclosure you are trying to prevent. Use synthetic material for adversarial testing and approved local inspection for actual release copies. Repeat the test when the tool, export settings or document format changes. Acceptance should attach to the defined workflow and file types, not become a permanent badge for every future feature carrying the same product name.
Build a small test pack whose hidden content you already know.
UK disclosure duties do not disappear behind an AI feature
The ICO's guidance on disclosing documents securely covers hidden personal information and accidental breaches. It expressly includes sending documents to customers and responding to information requests, not just publishing material on a website. It also says organisations remain responsible for their obligations under the UK GDPR and Data Protection Act 2018. The page was published in July 2025 and is marked under review following the Data (Use and Access) Act; it should not be presented as a new November 2026 rule.
For a UK business, that means technical removal is only one part of the decision. You still need an appropriate reason to disclose the remaining personal information, a suitable recipient and a secure delivery route. Removing a name does not necessarily anonymise a document if the surrounding details identify the person. Conversely, indiscriminate removal can undermine a legitimate information request. Escalate difficult decisions to the person responsible for data protection rather than turning a model's confidence into legal authority.
A recent commercial perspective comes from Jazz Security's October 2026 discussion of AI PDF tools. It distinguishes approved organisational accounts from personal or free upload routes. Treat this as vendor commentary rather than independent assurance or a blanket product recommendation. Its useful operational question is whether the account and upload path your employee actually uses fall within the controls you reviewed.
Before using cloud-based redaction, check the permitted data, processing arrangements, retention and access conditions for that specific service and plan. An approved PDF editor does not automatically approve every AI feature or external converter. If an accidental disclosure occurs, use your established incident process to assess containment, risk and any notification obligations. Do not rely on sending a corrected attachment as proof that the original information has been recovered from every recipient or downstream system.
A redaction tool assists a disclosure decision; it does not own it.
Keep the process proportionate, but make release ownership explicit
The reasonable objection is that a small business cannot turn every attachment into a forensic investigation. That is true. A public brochure and a sensitive employee case file should not have identical review overhead. The answer is to set proportionate routes, not to substitute a pleasant preview for evidence. Start with the document types where a failed redaction would cause real harm, then define a repeatable release checklist for those types.
For a low-volume team, an approved tool, a trained operator and a second check on sensitive releases may be enough. For repeated bulk disclosures, you may need automated detection and extraction checks alongside human review of uncertain cases. Use the test pack to decide where automation genuinely helps. Avoid commissioning a bespoke agent before checking whether existing licensed redaction and sanitisation functions meet the requirement. There is no advantage in rebuilding a mature file operation around a conversational interface.
What this means in practice is giving one person responsibility for the final release copy. That owner should know the disclosure purpose, the agreed exclusions, the tool and settings used, and the checks completed. Keep a concise audit record without creating another uncontrolled copy of the sensitive material. A document reference, review date, reviewer and result may be more useful than pasting withheld personal details into a ticket or an AI conversation.
Measure useful outcomes rather than the number of black bars produced. Track missed candidates in testing, recoverable information in output checks, review time and instances where staff picked the wrong file. If a file type repeatedly fails, suspend that route and use a proven alternative while investigating. The business benefit is not simply faster redaction. It is being able to share the right information confidently, without allowing a fast-looking AI step to conceal an unfinished document-handling job.
The reviewer should be able to explain what was removed and how the output was checked.
Key Takeaways
- Separate sensitive-information detection, permanent removal and release verification.
- Test the exact workflow with synthetic visible text, OCR content, comments, properties and attachments.
- Inspect the saved release copy locally rather than uploading confidential originals to a public AI checker.
- Check cloud processing and account controls for the particular AI feature, not just the PDF product.
- Assign a release owner and repeat acceptance checks when tools, export settings or file types change.