
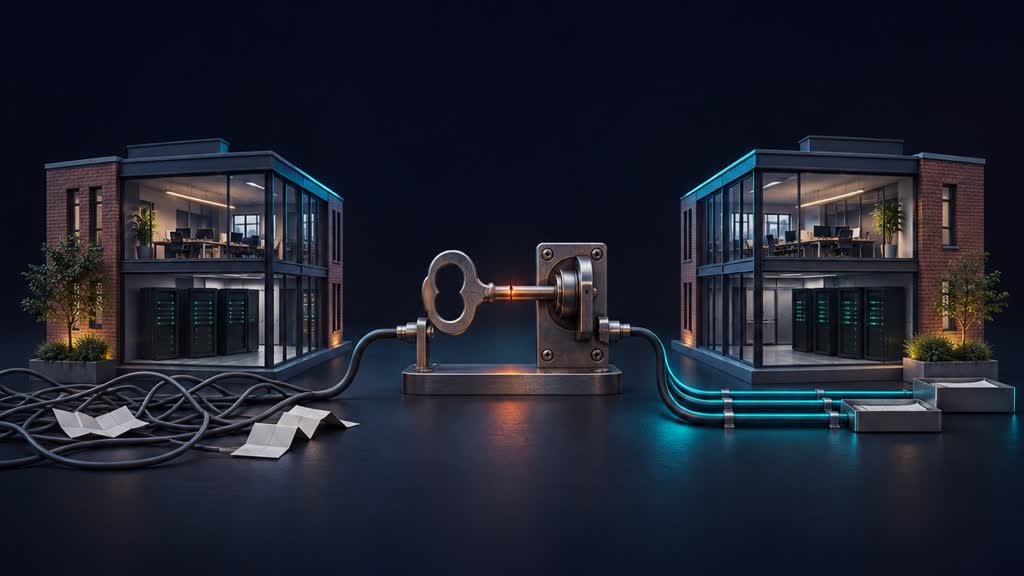
Your backup AI service may sit in a different UK region and still need the same broken login, routing service or model endpoint. Two locations are not proof of two independent recovery paths.
Count independent recovery paths, not pins on a map
A supplier shows you two UK locations. Your production AI service runs in one and a standby runs in the other. That sounds like a sensible answer to regional disruption. It may be, but the map tells you where equipment sits, not everything that equipment needs before a member of staff can finish a job. Both deployments might use one identity tenant, one model gateway or one central configuration service. If that common dependency fails, moving the workload may change its location without restoring its usefulness.
The government's Cloud Challenge Book 2026, updated on 29 October, makes this distinction unusually concrete. Infrastructure challenge 4 calls for at least two fully-featured regions for organisations seeking UK jurisdiction and multi-region resilience. Separately, cyber challenge 5 flags dependencies on single regions for global services and constant connectivity. The important word is fully-featured. A second building does not necessarily supply an independent version of every service your application requires.
For a business owner, the useful question is therefore not whether a supplier has two UK regions. Ask which specific failures the arrangement is designed to survive. A regional storage interruption, an identity outage and an unavailable model service are different scenarios. A system can handle the first brilliantly and fail completely on the others. Record that distinction before anyone describes the arrangement as resilient.
This does not mean every smaller business needs two cloud deployments. It means the protection you buy should match the disruption that would hurt you. A documented pause and a usable manual process may be more proportionate than an elaborate standby with the same hidden dependencies.
Two locations are not proof of two independent recovery paths.
Draw the shared services between the two sites
Start with one business task, such as preparing a service quotation from approved customer records. Draw the route from the staff member's login to the final saved quotation. Include the application, identity provider, document store, search index, model endpoint, secrets store and system that receives the result. Then draw the backup route alongside it. Wherever the same service appears on both paths, mark it as a shared dependency for investigation.
Do not assume that every shared service is a single point of failure. An identity provider may already have strong distributed resilience. The exercise identifies what needs evidence, not what must immediately be replaced. Ask whether the dependency is regional or global, whether an existing session keeps working during disruption, and whether a new operator can sign in. A running application and a recoverable application are not the same thing.
Include services that appear administrative. If changing the model destination requires a management portal that is unavailable during the incident, the documented failover instruction cannot be carried out. If both regions retrieve fresh credentials from the same inaccessible store, an unused standby may fail at the moment it starts. DNS, certificates, network access and billing or quota controls can also matter, depending on the architecture. Treat these as questions for your actual supplier, not universal claims about cloud platforms.
In practice, keep the map simple enough for the service owner to explain without the original implementer present. For each shared dependency, write the owner, the impact of failure and the evidence supporting the proposed response. A short list of unresolved assumptions is more useful than a polished diagram that silently treats everything outside the regional boxes as somebody else's problem.
A recovery map should show what both regions depend on, not just where they differ.
Check that the second region can do the same permitted work
Regional availability and feature availability are separate purchasing questions. Your application may be deployable in two places while its chosen model, search feature or document-processing service is available in only one approved location. A backup route may exist technically but rely on processing elsewhere. That can be acceptable for some work and unacceptable for other work. The decision belongs in the design, not in an improvised incident conversation.
The Council for Science and Technology's advice published on 19 October 2026 treats sovereignty as sufficient agency across the AI value chain, including resilience under duress. Its four recommendations cover capability, governance and access, rather than a blanket requirement to build everything domestically. This is national policy advice, not a new legal rule for small businesses. Its practical lesson is to specify the outcome and dependencies before choosing infrastructure.
Ask for a capability comparison for the primary and backup routes. Can both use the approved model capability, retrieve the right documents, apply permissions and save an auditable result? Are enough compute capacity and service quotas actually available? Does the backup require a different model, and if so has that model passed the relevant business checks? A supplier's regional service catalogue is a starting point, not proof that your configured application works there.
Keep legal and contractual checks separate from operational tests. A successful technical failover does not establish compliance with UK GDPR, customer confidentiality clauses or your agreed processing restrictions. Equally, a UK location alone does not answer every jurisdiction or access question. Have the appropriate owner review the actual destination and terms before sensitive information enters the backup route.
A backup that only works by relaxing the data boundary is a different service.
Test a shared failure without causing a real incident
A standard regional failover demonstration often proves that traffic can move while everything else remains healthy. That is useful evidence, but it does not answer the shared-dependency question. Add a controlled test that makes one common service unavailable to the test environment. Choose a realistic scenario, obtain the technical owner's agreement and avoid changing shared production services. Use synthetic or appropriately approved data and a reversible setup.
For example, test what happens when the application cannot reach its normal model gateway. Does the second region use an approved independent route, pause cleanly or repeatedly retry? Then test whether a different authorised operator can start recovery without an existing browser session. Where suitable, simulate loss of access to the normal management interface. The aim is to discover which steps depend on the very service presumed unavailable.
In practice, observe the whole quotation workflow rather than a health indicator. A server can return a healthy response while customer-document retrieval fails. A model can produce fluent text from stale records. The quotation may reach the CRM twice if queued work is replayed after recovery. Include permissions, document freshness, duplicate prevention and the final saved record in the acceptance checks. Stop the exercise if it risks uncontrolled writes or moving information to an unapproved destination.
Write down elapsed recovery time, the work completed, work waiting and any manual intervention. These are observations from your exercise, not a guarantee about every future outage. Repeat the relevant tests when a shared dependency or recovery procedure changes materially. You do not need to simulate every conceivable catastrophe; you need credible evidence for the failures your continuity plan claims to handle.
Test the missing dependency, not merely the button labelled failover.
Buy proportionate independence rather than duplicated complexity
The obvious counterargument is that independent infrastructure costs money and creates work. That is correct. A small firm should not buy a second cloud, duplicate every database and maintain spare AI capacity merely to make an architecture diagram look reassuring. The right comparison is between the value of continuity and the full operational burden of achieving it. Include training, patching, access management, testing and the possibility of inconsistent records.
The Cloud Challenge Book reports that 60% of UK businesses use cloud services and describes a market worth over £10.5 billion. Those are figures reported by that government publication, not measurements of your own exposure or proof that multi-cloud is the answer. Cloud adoption makes the dependency question relevant to ordinary firms; it does not make every firm a critical national service.
For a low-urgency drafting assistant, the proportionate response might be to pause generation and let staff use approved templates. For time-sensitive operational work, you may need a tested independent model route or enough manual capacity to cover a realistic interruption. Hosting an open-weight model yourself is another possibility, but it introduces hardware, licence and operating responsibilities. Check maintained tools and existing supplier features before commissioning a custom recovery layer.
A useful procurement discussion separates three levels: tolerate a pause, continue a reduced service, or restore the normal service within an agreed period. State which level applies to each workflow. Ask suppliers for evidence at that level rather than a generic promise of sovereignty. If your team cannot run the backup confidently, additional infrastructure may increase the number of things that can fail without materially improving the business outcome.
A second provider can add independence, but also another system your team must operate.
Turn the dependency map into an accountable operating decision
Give the map and test results to one named business owner. That person should understand which shared dependencies remain, which failures the service is designed to tolerate and what happens when those assumptions break. Technical suppliers can provide evidence, but they cannot decide how much interrupted work your business should accept. The operating decision needs a clear owner rather than agreement spread vaguely across IT, procurement and department managers.
A recent Aventail guide published on 16 November separates data, operational and model sovereignty. It is a supplier-authored explanation, not independent certification, but that distinction is useful: location, operating control and model control answer different questions. Our focus here adds a further purchasing test. Two locations only improve continuity to the extent that the recovery route survives the dependency you lose.
Prepare a one-page record with the workflow, permitted processing destinations, shared dependencies and tested recovery behaviour. Add the person authorised to activate the backup, the communication route and the condition for returning to normal. If a restricted workflow must stop rather than leave the UK, say so plainly. If the fallback produces drafts only and requires human review before anything is sent, preserve that limit throughout recovery.
Start this week with the workflow whose interruption would create the most expensive queue of unfinished work. Ask the supplier to walk its recovery path with you and identify one common service to test safely. Record the gaps without pretending they are resolved. The aim is not perfect independence from the global technology industry. It is an honest, evidence-backed understanding of what continues, what pauses and who acts when two reassuring UK map pins stop being enough.
The decision is not whether you have a backup, but which interruption you can actually survive.
Key Takeaways
- Map identity, management, DNS, secrets and model dependencies shared by your primary and backup UK regions.
- Check feature availability, reserved capacity and permitted data destinations for the actual backup workflow.
- Run a controlled non-production test that removes a shared dependency, not just the primary regional application.
- Measure completion, permissions, data freshness and duplicate writes alongside recovery time.
- Assign one business owner to decide whether each workflow pauses, degrades or recovers fully.